Supported data sources
What you can connect to Tattva — uploaded files, documents and BigQuery tables — and the limits of each.
You connect data on the Sources page. It has four tabs: All, Upload, Apps and BigQuery.
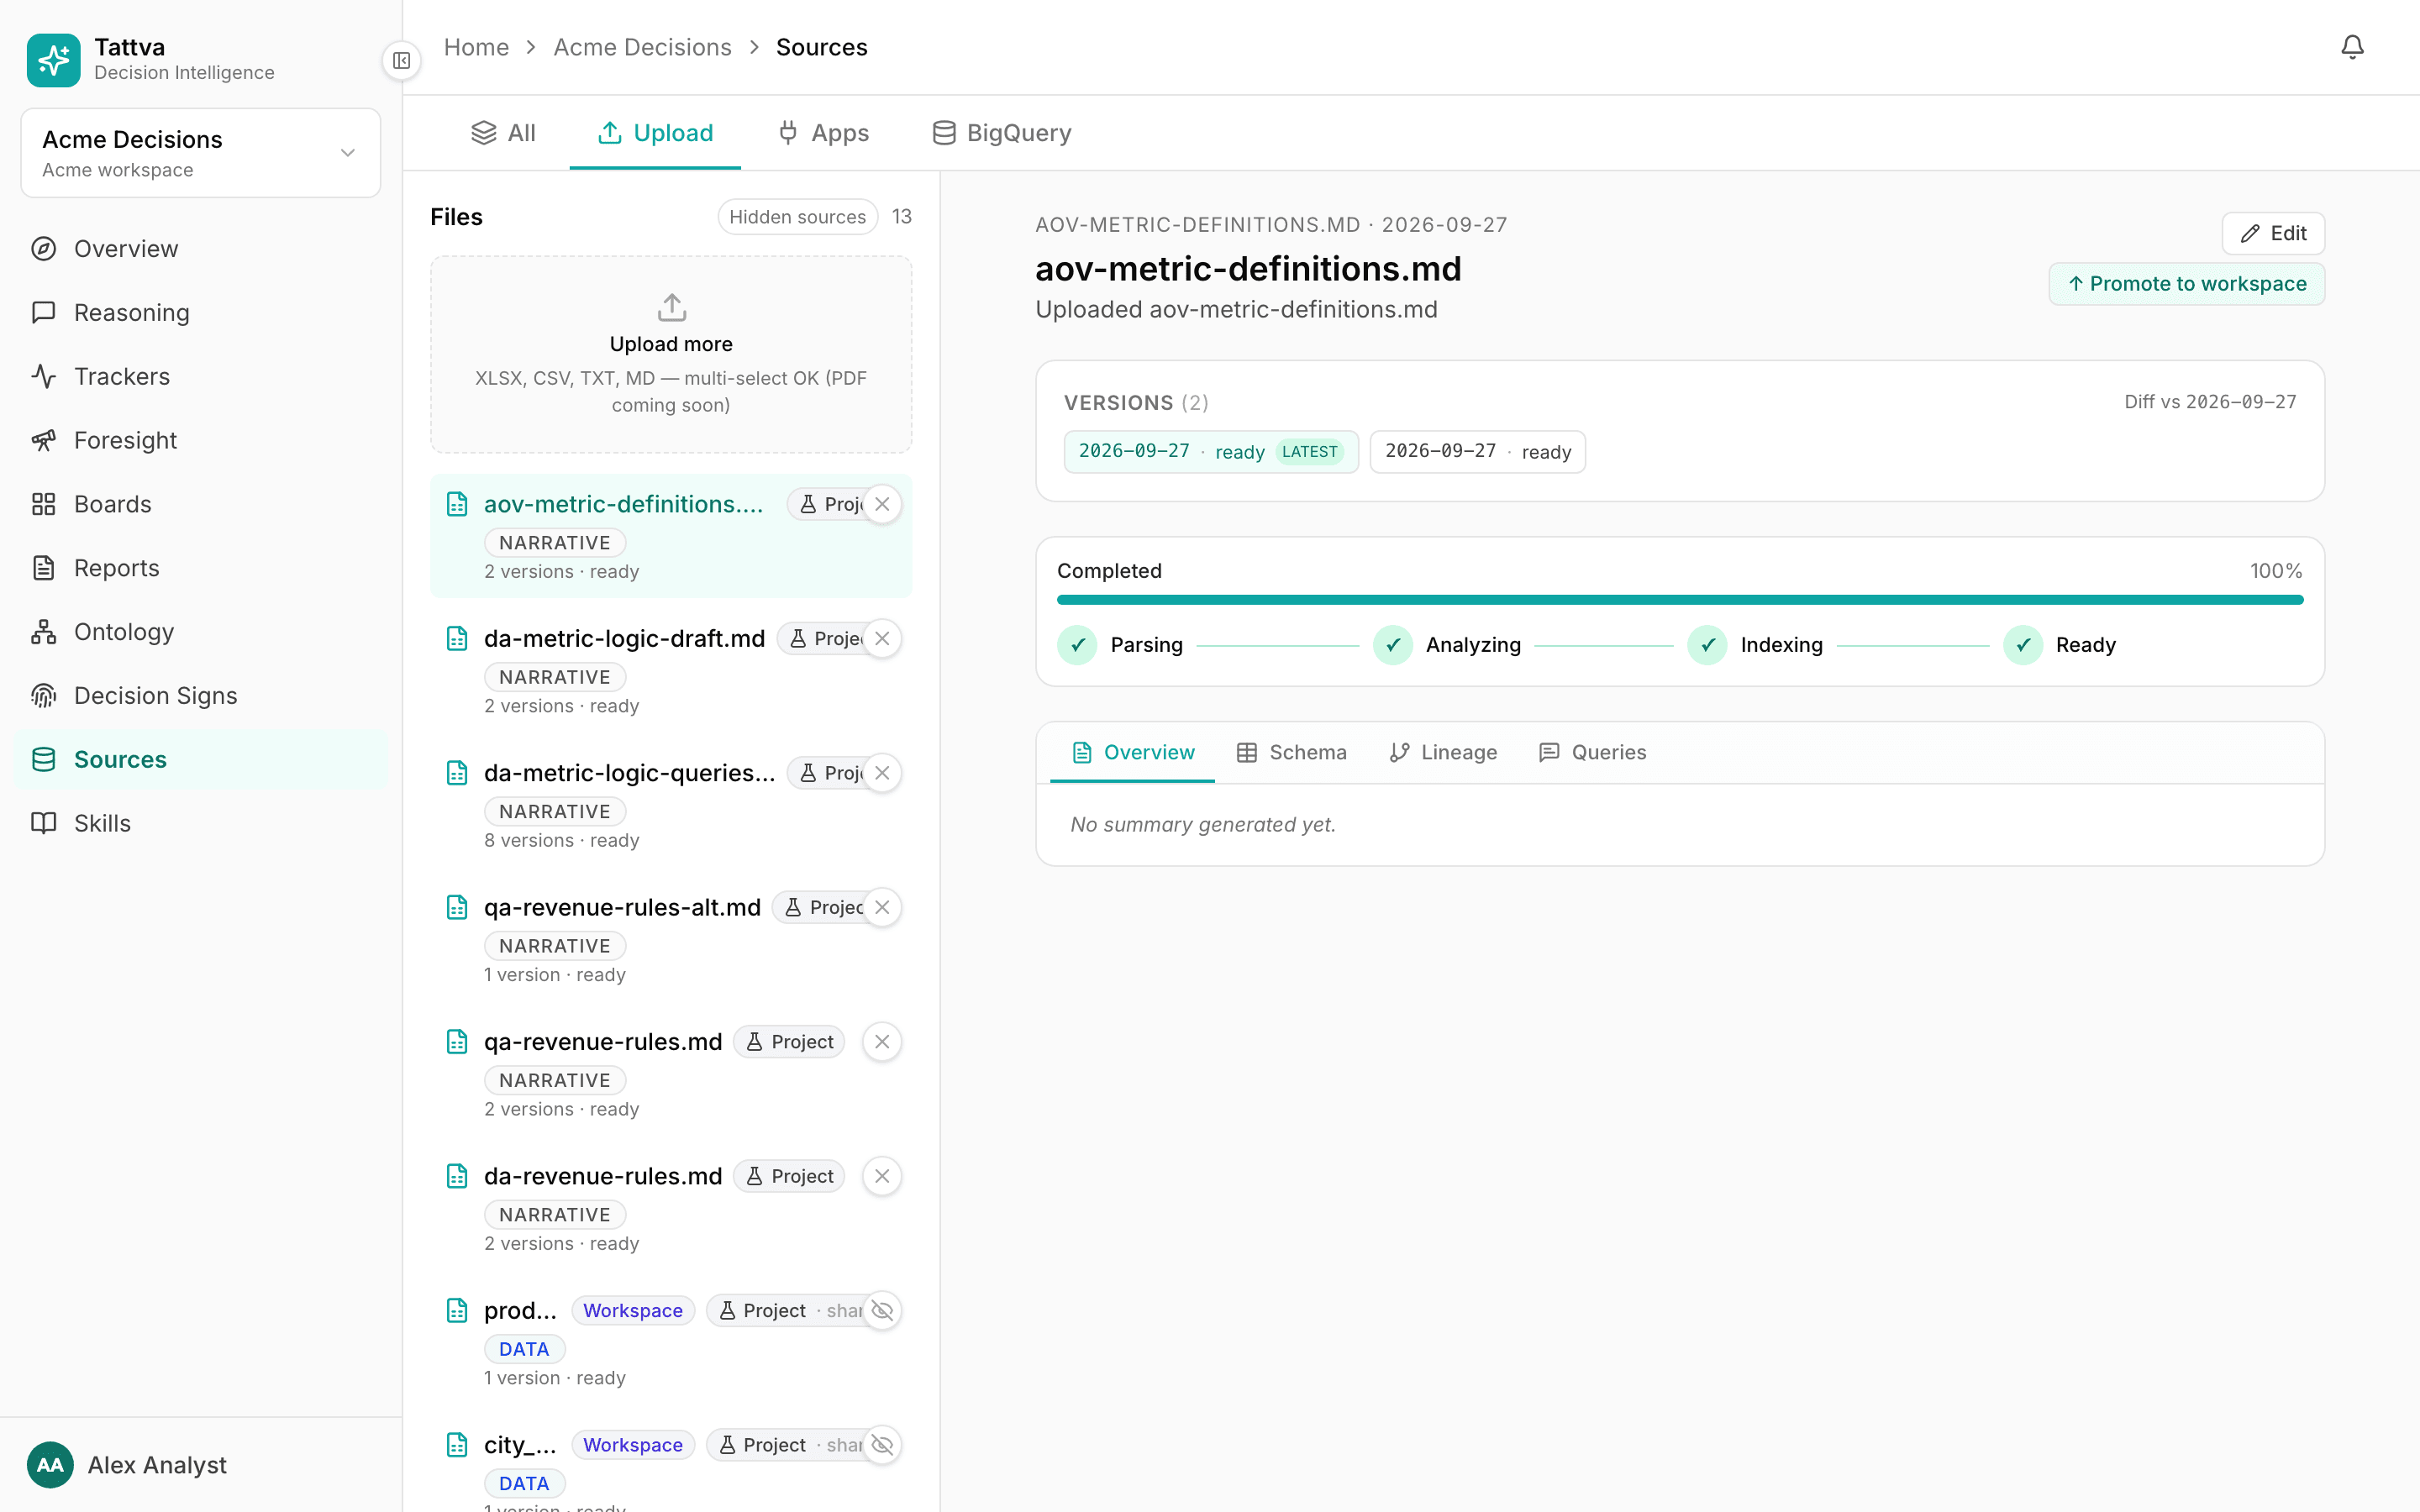
Uploaded files
Drop files on the Upload tab, or click to pick several at once.
| Type | Extensions | What happens |
|---|---|---|
| Spreadsheets | .csv, .tsv, .xlsx, .xls | Each file becomes a source. Tattva reads the columns, infers types, profiles them and describes them. In Excel files, every sheet is read. |
| Text documents | .md, .txt | Stored word for word. A document that defines metrics is read by the next ontology build; see Write a metric document. |
| Web pages | .html | The text is kept and the markup removed. It can be searched, but the ontology build does not read HTML files as metric documents. Save metric documents as .md or .txt. |
The file picker also lets you choose .json and .parquet files. They go through the same reader as spreadsheets, which is built for CSV and Excel. Convert them to CSV, or load them into BigQuery, before relying on them.
PDF is not supported. The drop zone mentions PDF, but a PDF upload is refused. Save the text as .md or .txt instead. Word documents, audio files and images can't be uploaded.
Processing
After upload, a spreadsheet goes through Parsing, Analyzing and Indexing to Ready. If something goes wrong you'll see "Pipeline failed — check logs." on the source.
Limits
- Up to 200 MB per file (50 MB on deployments without cloud storage). Larger data belongs in BigQuery.
- When the agent queries an uploaded file, it reads up to 10,000 rows per query.
- Uploading a file with the same name again adds a new version of that source.
- If the Workspace Library already holds a source with that file name, your project uses the shared one instead of creating a copy.
Tips for clean files
- One header row at the top.
- One row per thing (per order, per customer). Avoid pivoted summaries.
- Dates as
YYYY-MM-DD. - Real column names, not abbreviations only you understand.
- Raw rows, not pre-aggregated totals.
BigQuery
The BigQuery tab connects tables from your warehouse. Tattva queries them where they are; rows aren't copied.
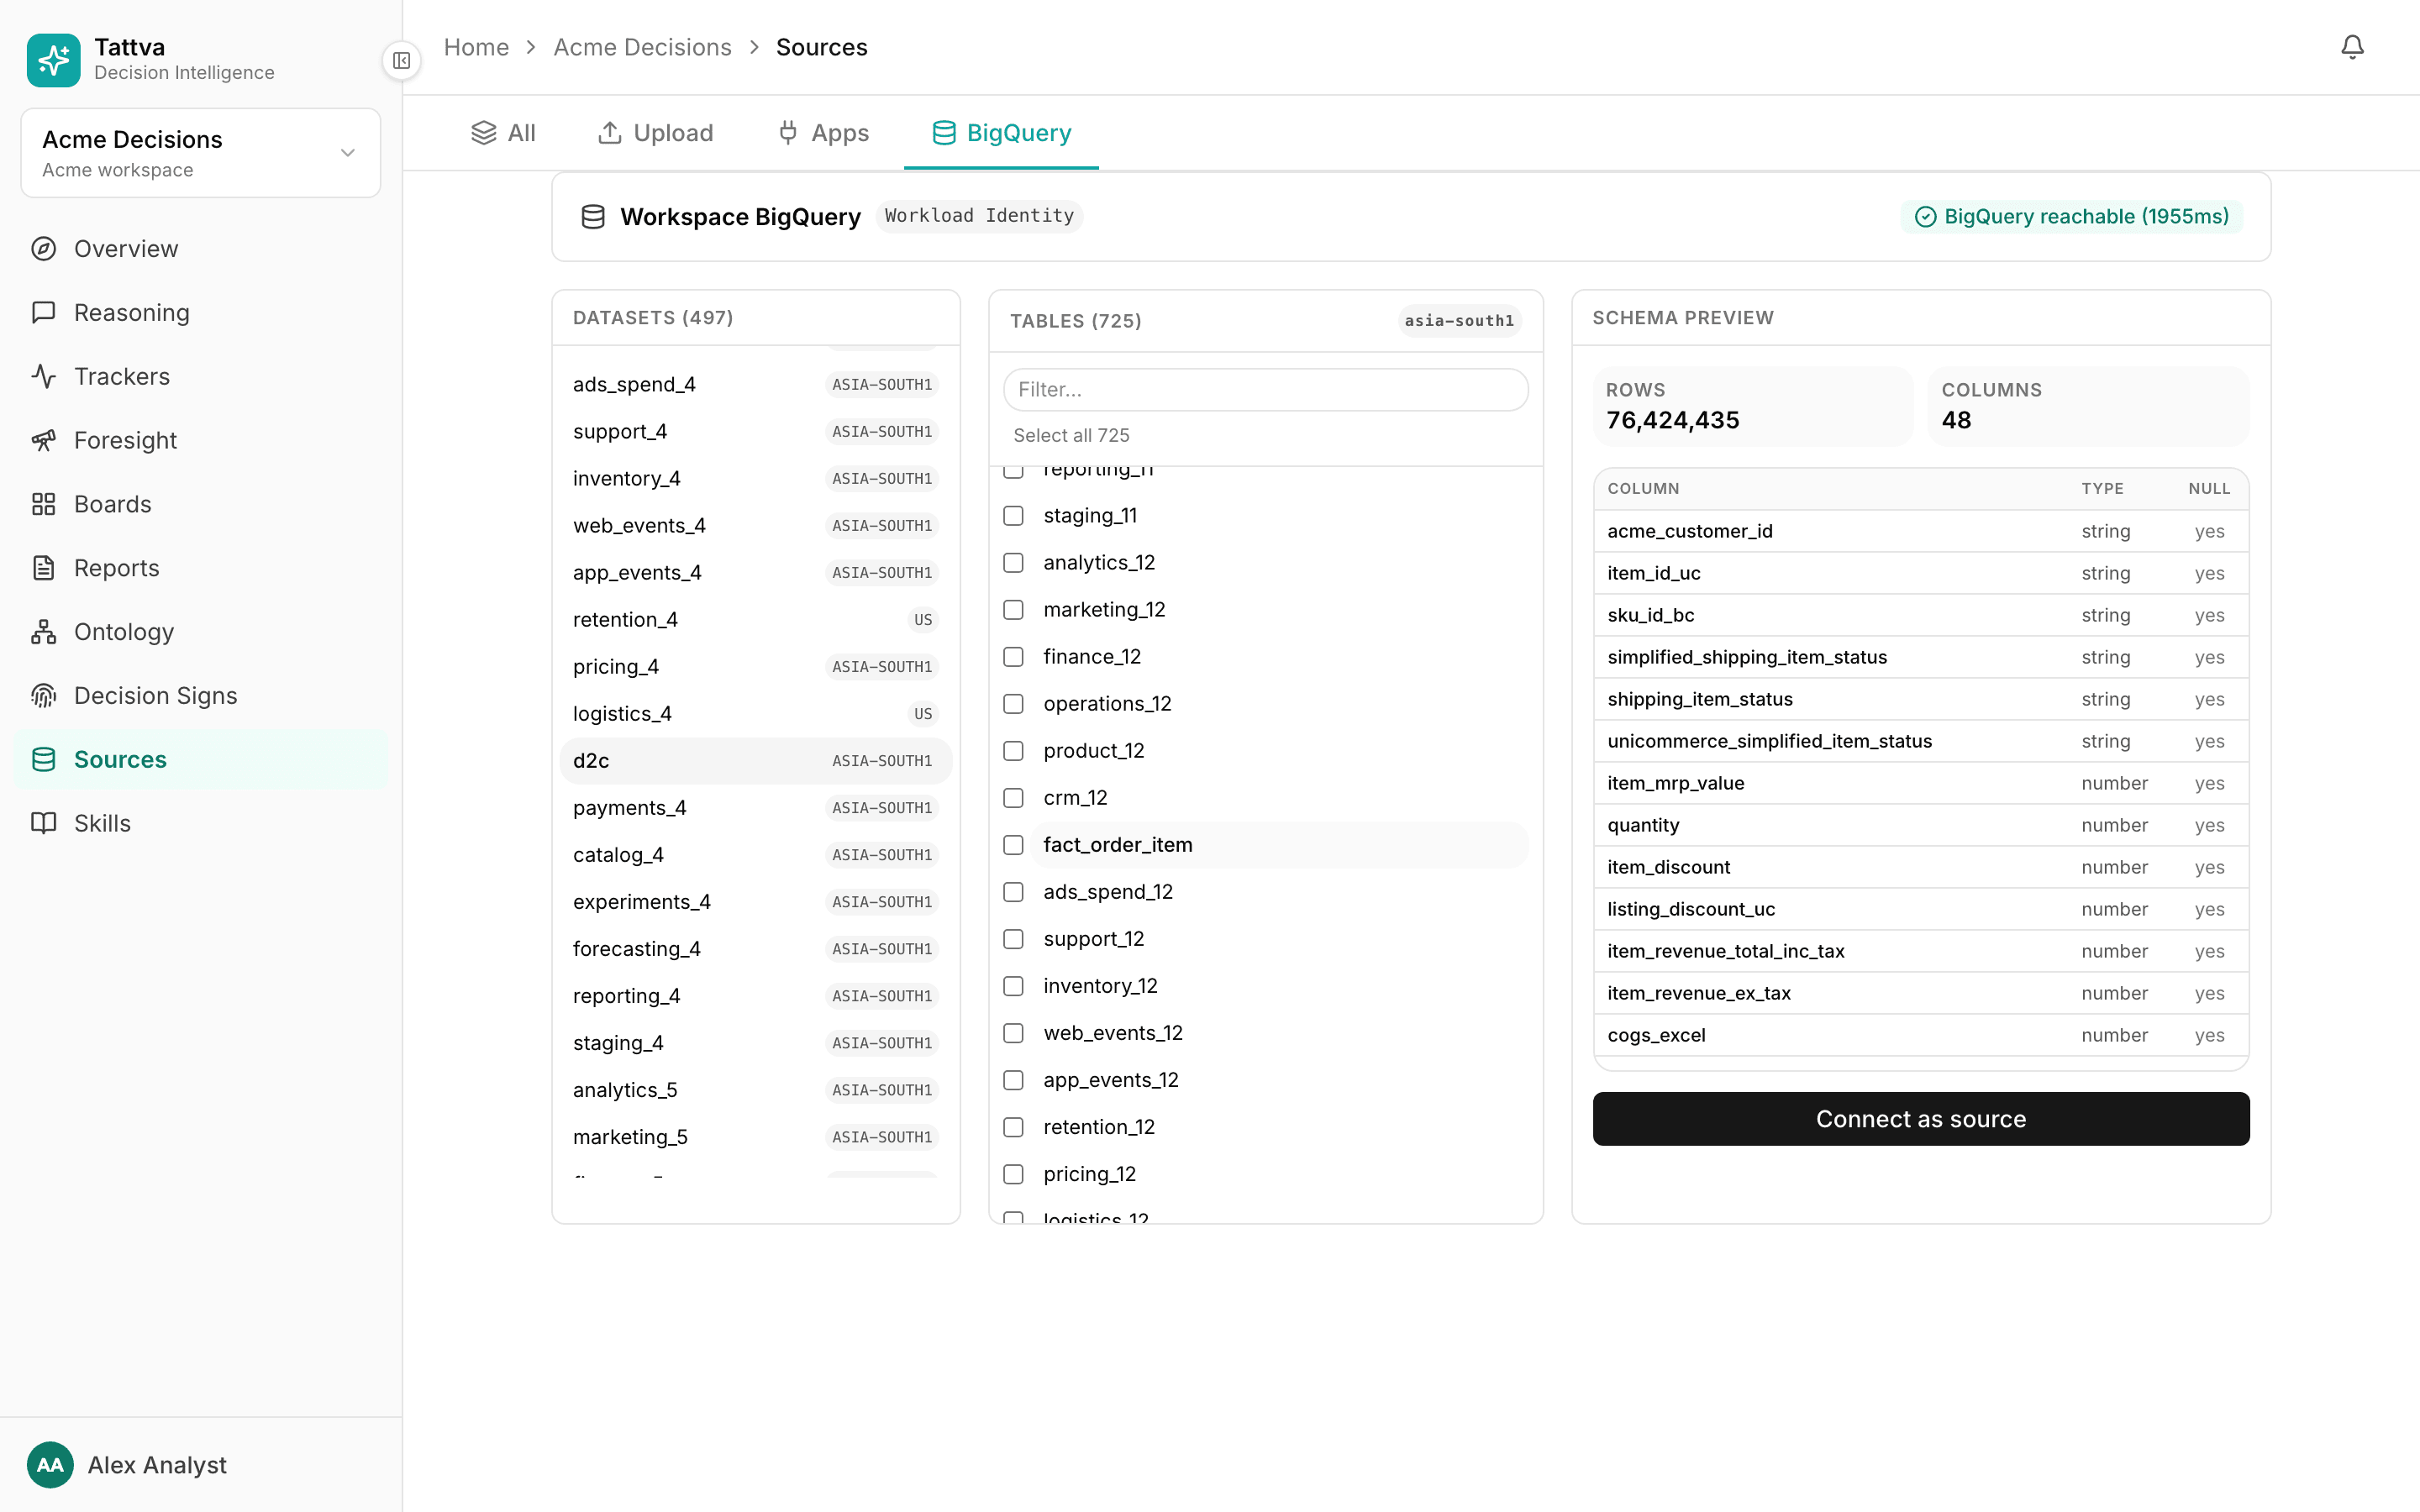
- Pick a dataset under Datasets.
- Pick one table to see its Schema preview, then click Connect as source. Or tick several tables and click Connect N as sources.
- Your platform operator sets up BigQuery access for the workspace: the Google Cloud project to use and the permissions of the workspace's cloud identity (shown as Workload Identity). There is no key to paste. If the tab shows an error instead of datasets, send it to your platform operator.
- Queries run on your BigQuery account and are billed there. Each query is capped (20 GiB scanned and 2 minutes by default), and BigQuery rejects an over-budget query before it runs.
- Stored metric definitions run only on BigQuery. A metric defined over an uploaded file can use a formula, not a stored query.
- Tattva never joins a BigQuery table with an uploaded file in one query.
Apps
The Apps tab has no connectors. To bring in data from another tool, export it to a file or load it into BigQuery.
What Tattva doesn't do
- Write to your data. Tattva only reads. Stored definitions must be a single read-only
SELECT, and the agent's queries on uploaded files are read-only. - Connect to other warehouses or databases. BigQuery is the only warehouse.
- Pull from SaaS tools or streams directly. Export to a file or BigQuery first.
See also
- Connect data sources: the how-to.
- Connect and describe data: for data analysts.
- Tiers & limits